Guides
How-tos and strategic perspectives on building with small language models.
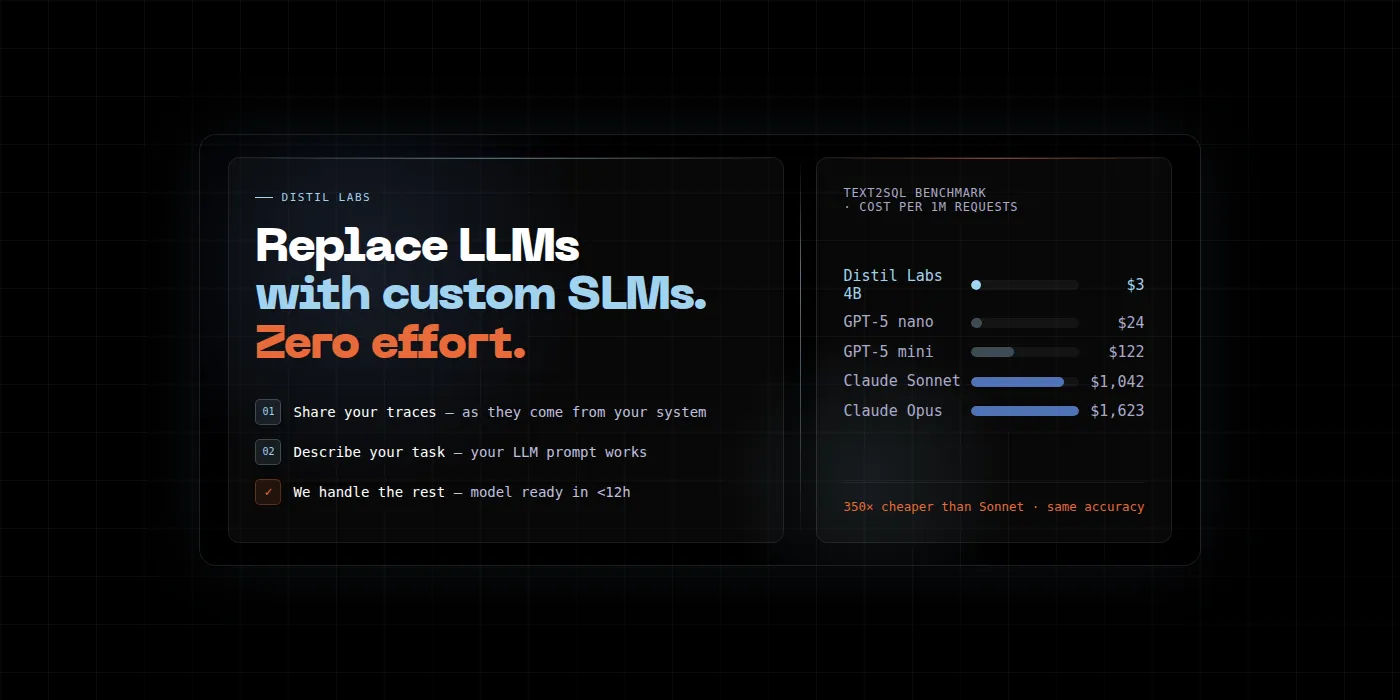
From Production Traces to a Faster, Cheaper, Accurate Model
Learn how to turn your production LLM agent traces into a compact specialist model that outperforms the original, with zero manual annotation and deployment in under 12 hours.
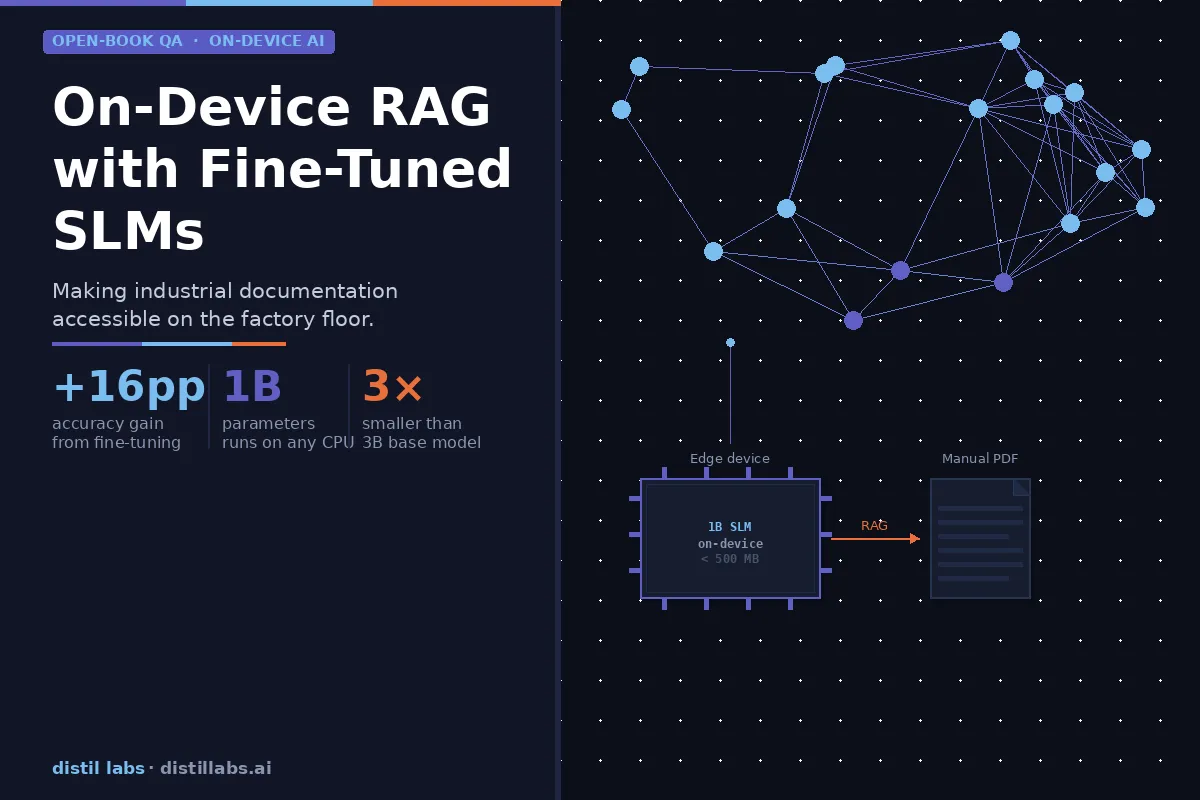
How SLMs Can Enable On-Device RAG - Making Industrial Machinery More Usable
Fine-tuned 1B parameter models can match the accuracy of 3B base models on domain-specific documentation, making on-device RAG viable for industrial equipment without expensive AI-optimized hardware. We tested this on a Siemens PLC manual and achieved a +16 percentage point accuracy gain through distillation.

The LLM in Your Voice Assistant Is the Latency Bottleneck. Replace It with an SLM.
Voice assistants on cloud LLMs are slow and expensive per turn. A fine-tuned SLM is cheaper and faster per request with equal-or-better accuracy on bounded tasks: brain-stage latency drops from ~700ms to ~40ms, and per-turn cost from cloud-API rates to server-amortized pennies.

Vibe-Tuning: The Art of Fine-Tuning Small Language Models with a Prompt
Fine-tuning is a pain – you need datasets, ML expertise, and a stack of GPUs just to get started. Not anymore. With model vibe-tuning, you go from prompt to production-ready model without these headaches. This blog post shows you exactly how to build one, starting with just a prompt.
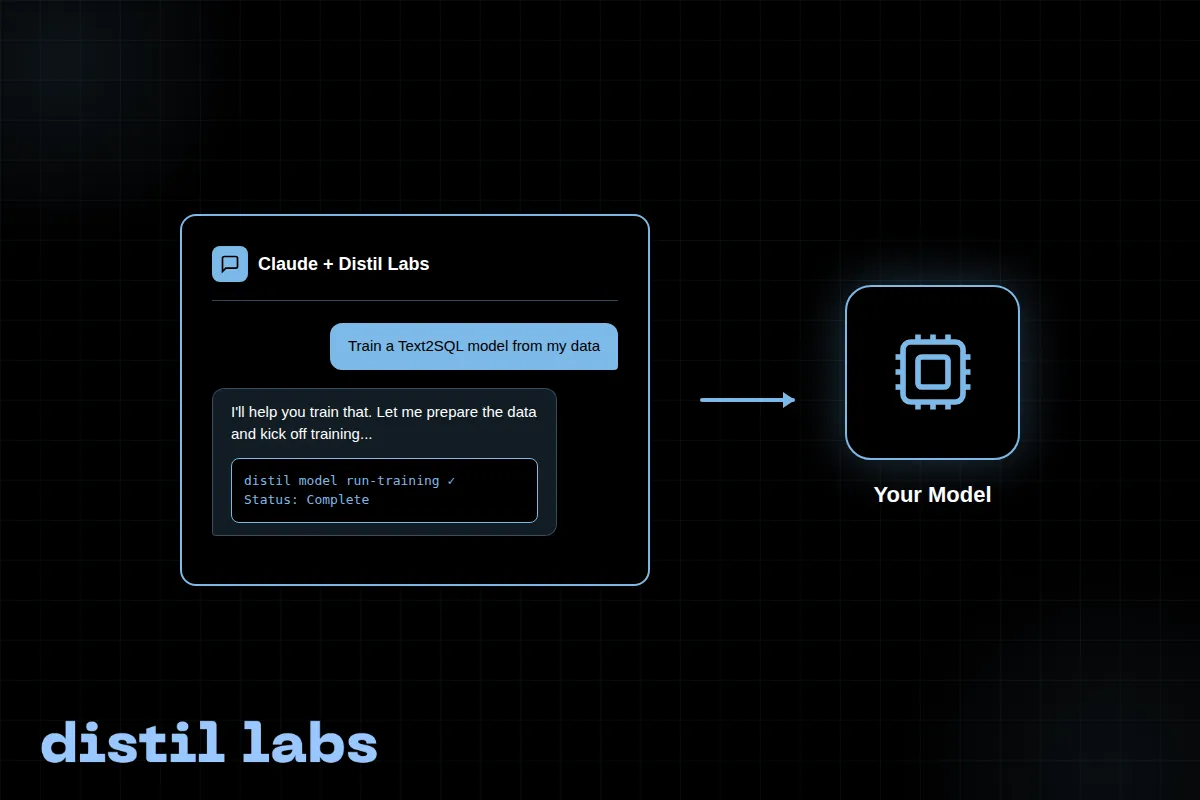
Train Your SLM with the distil labs Claude Skill
A step-by-step walkthrough of training a Text2SQL small language model using the distil labs Claude Code skill, going from raw conversation data to a working local model in a single conversation.

distil-PII: Family of PII Redaction SLMs
We trained and released a family of small language models specialized for policy-aware PII redaction that dramatically outperform their pre-trained counterparts.

distil labs: Small Models, Big Wins – Using SLMs in Agentic AI
How small language models can match or beat much larger LLMs when fine-tuned to well-scoped tasks, enabling faster, cheaper, and more private agentic AI workflows.
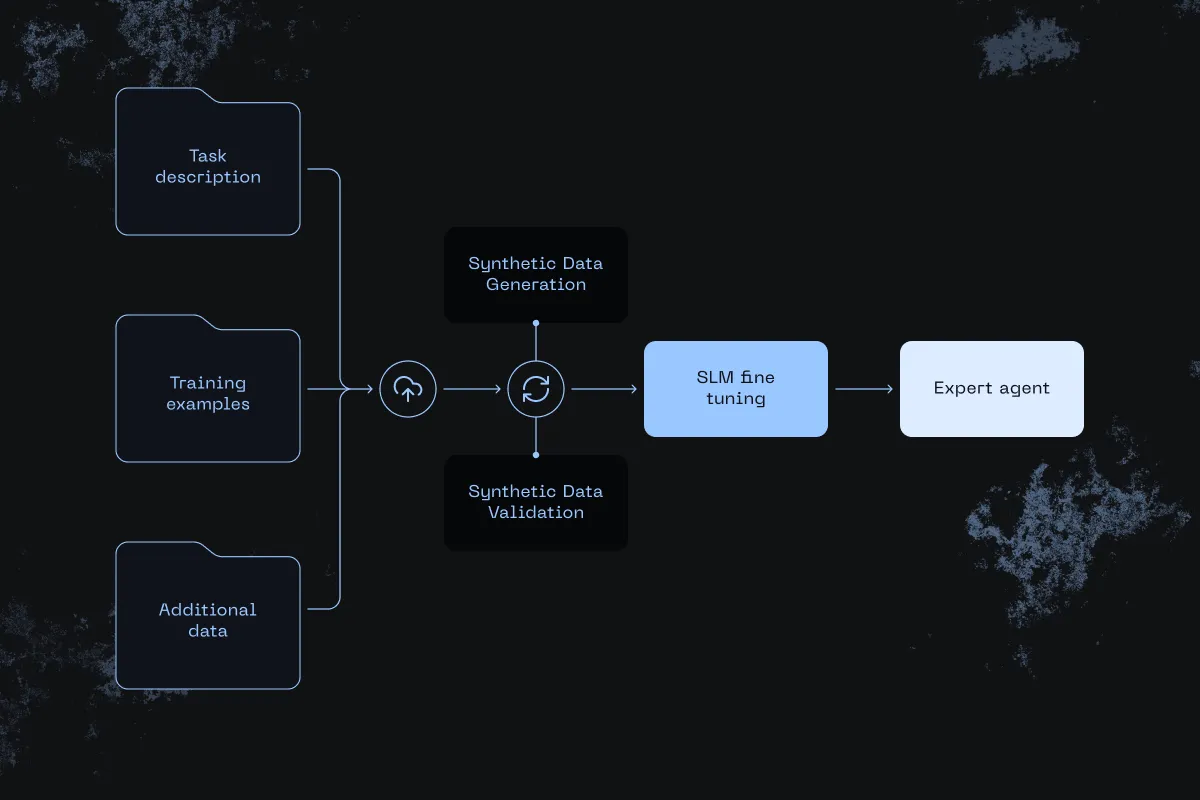
distil labs: Small Expert Agents from 10 Examples
An overview of how distil labs turns a prompt and a few dozen examples into a small, accurate expert agent that matches LLM-level results with models 50-400x smaller.